Phone
A mouth icon next to the microphone.
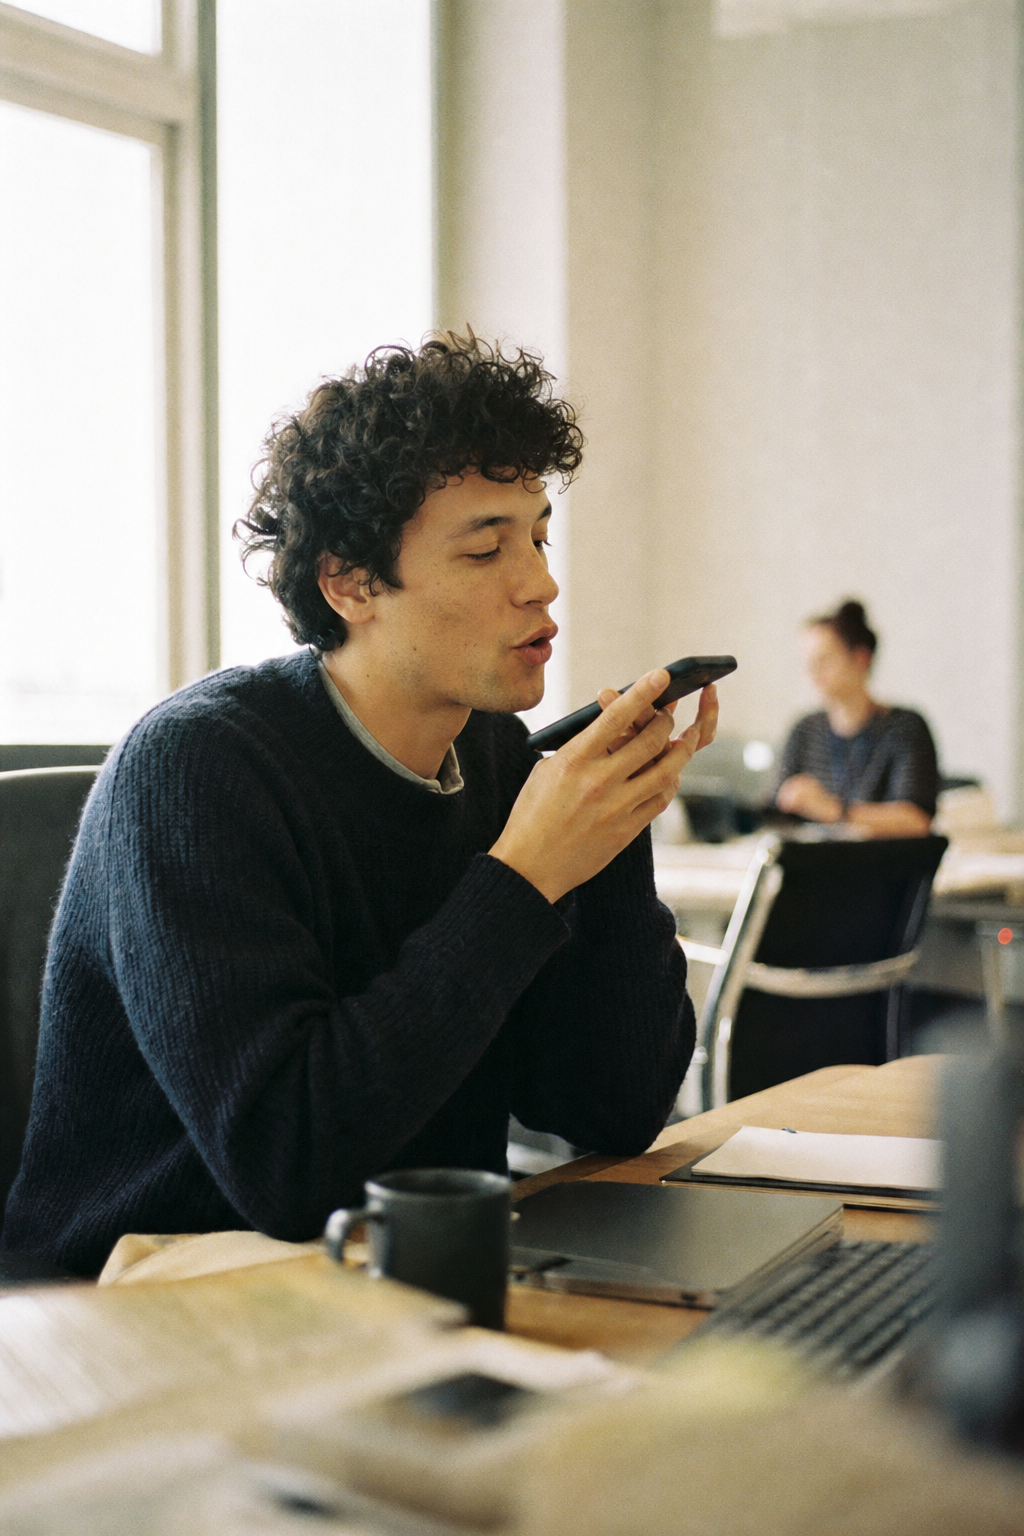
Add private dictation to any keyboard. Whisper or mouth silently, get text anywhere. Already working on iOS, Android, and Mac.
Voice, whisper, and silent input across phones, earbuds, glasses, XR, and cars. One adaptive speech layer using the microphones and cameras already in your devices.
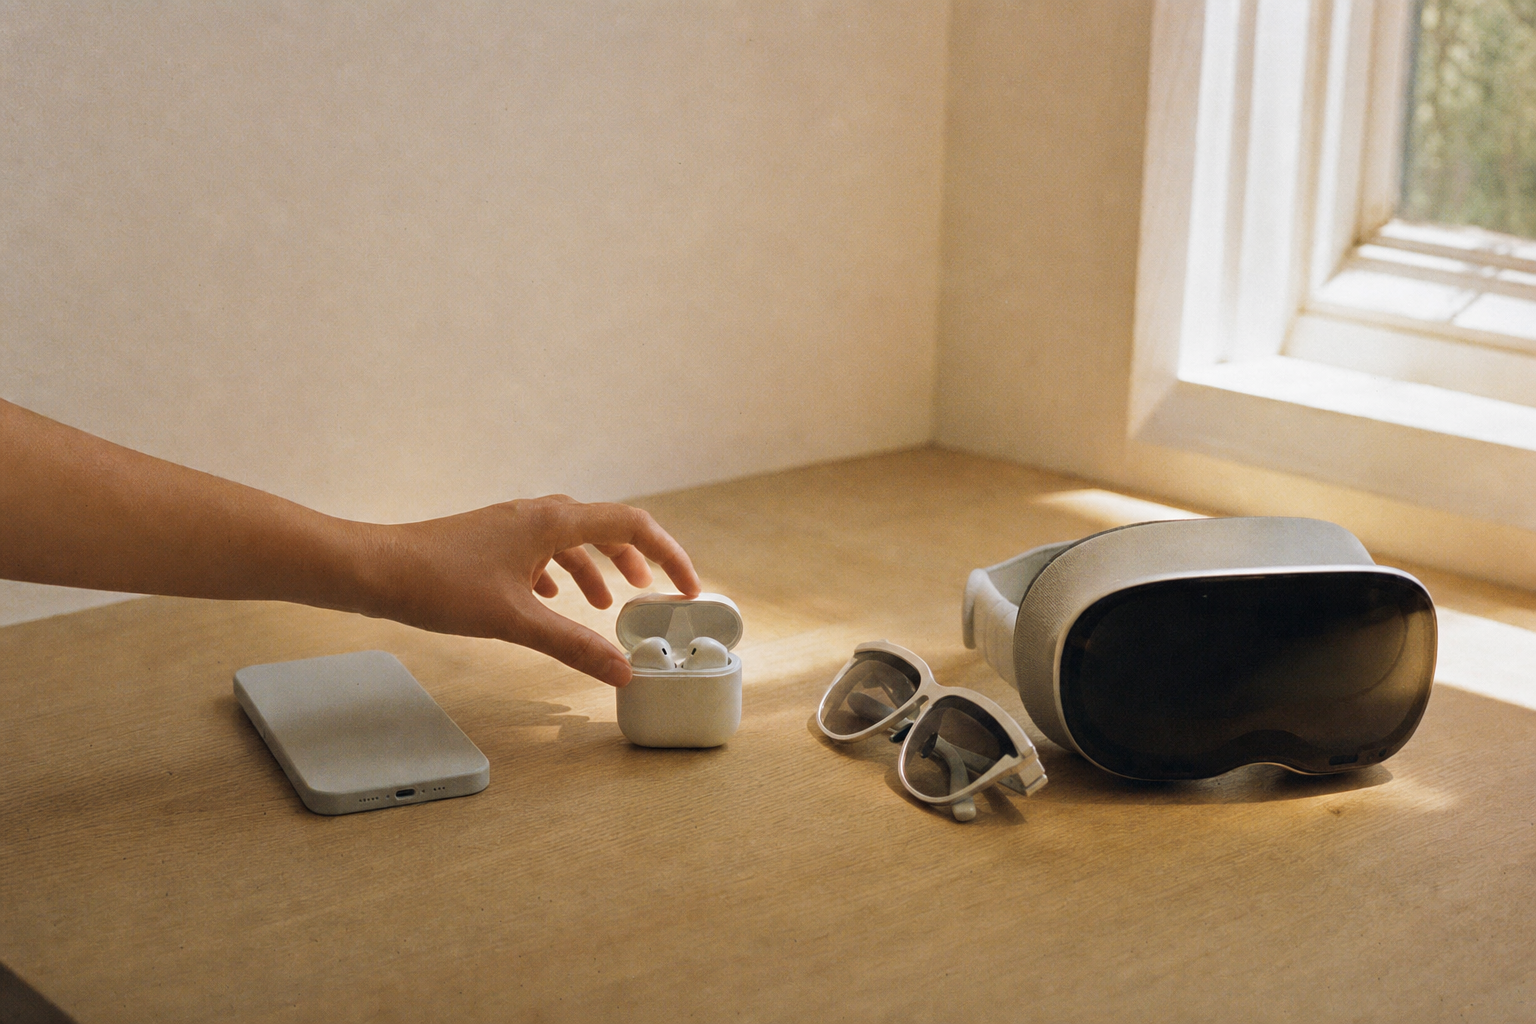
Every device your users own already has the sensors we need. We meet them wherever they are, at whatever volume they can speak.
Add private dictation to any keyboard. Whisper or mouth silently, get text anywhere. Already working on iOS, Android, and Mac.
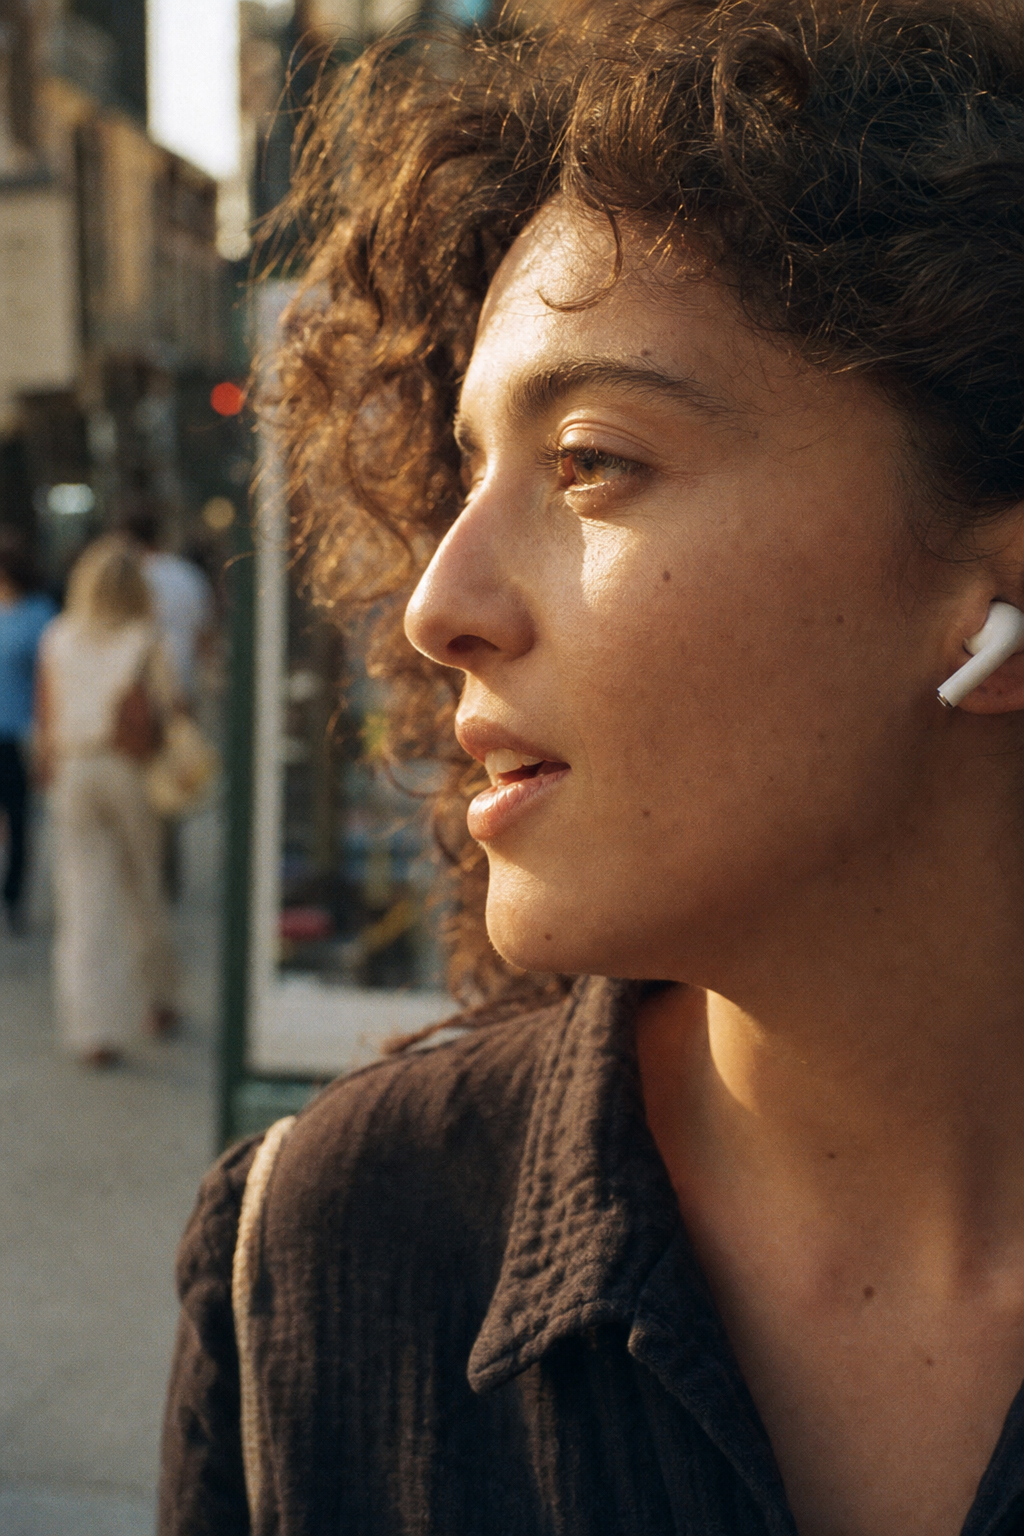
Target Speaker Extraction isolates and enhances the wearer’s quiet voice, even around noise and other speakers. Mic-only, no camera. Prototype running on AirPods today.
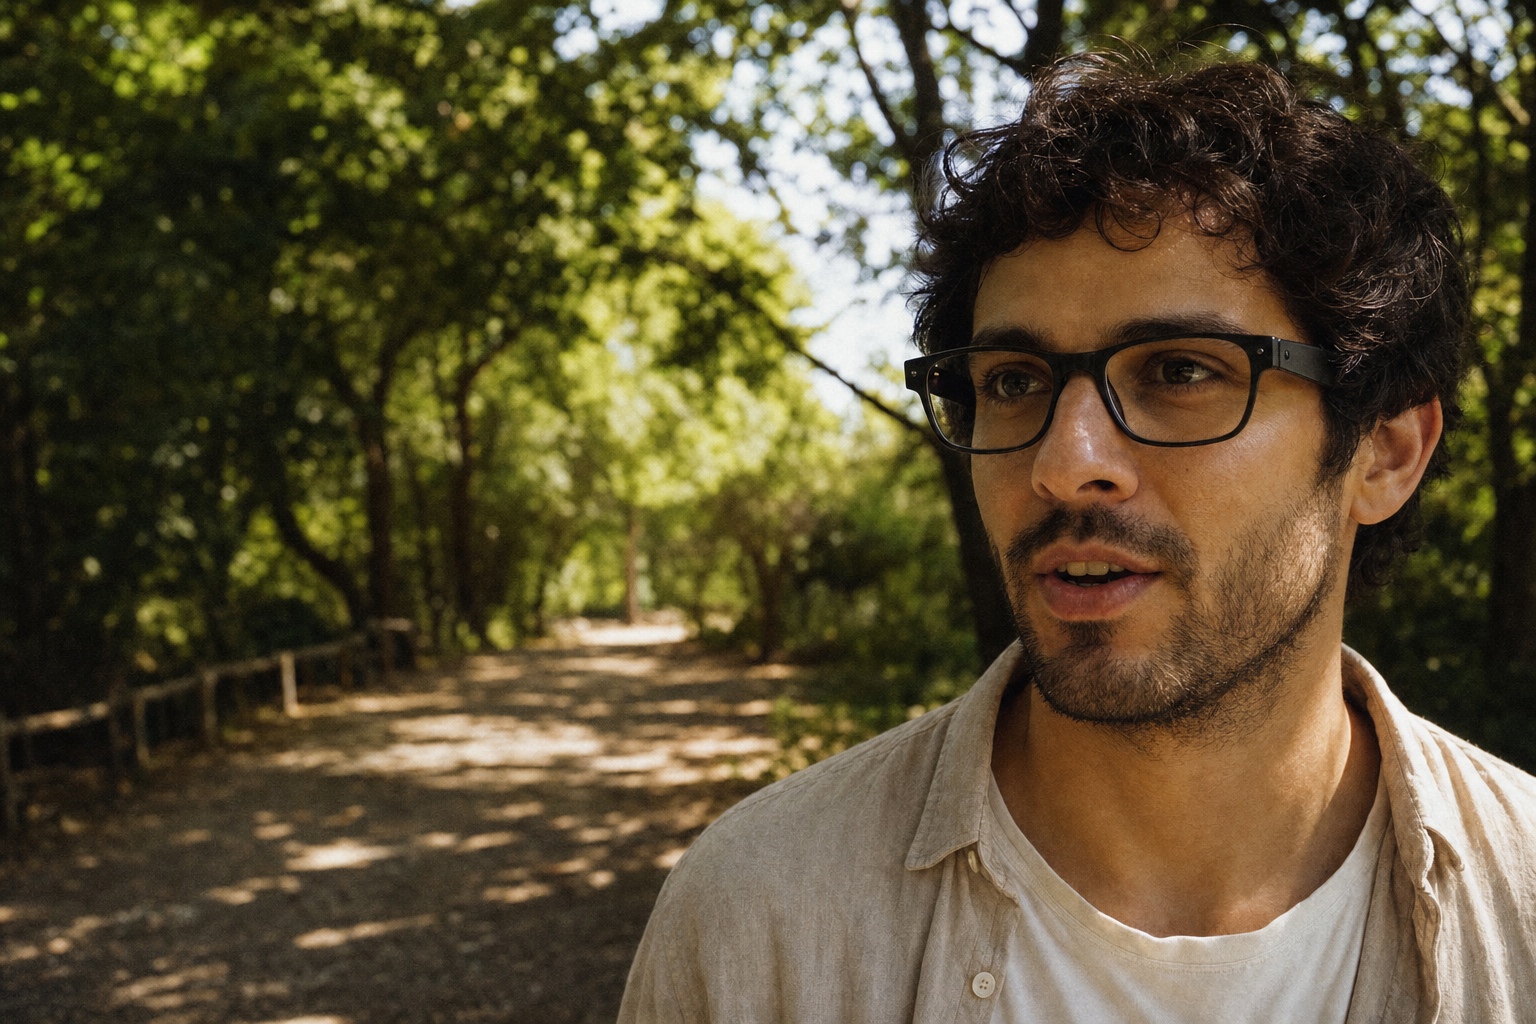
The same glasses that already have a pinhole camera and a beamforming mic array can run silent speech and whisper natively. Multimodal recognition, wearer targeting, and turn detection all improve when audio and vision fuse.
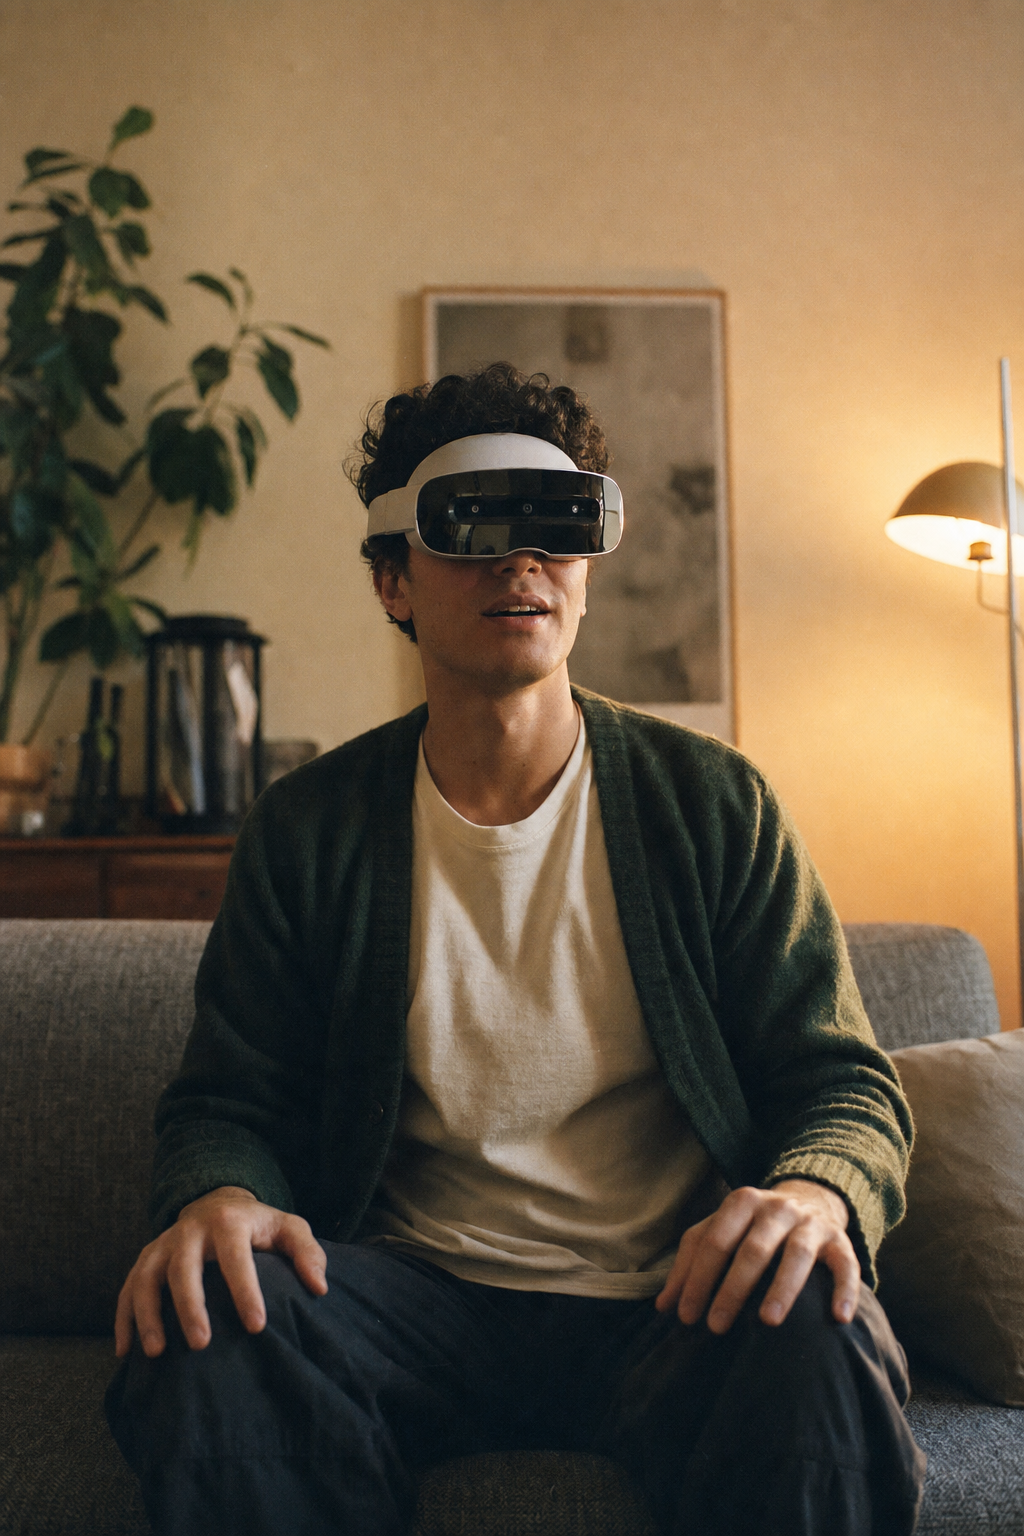
Talking out loud inside a headset is the least social thing about XR. Silent and whisper input make voice feel appropriate again, especially in shared spaces.
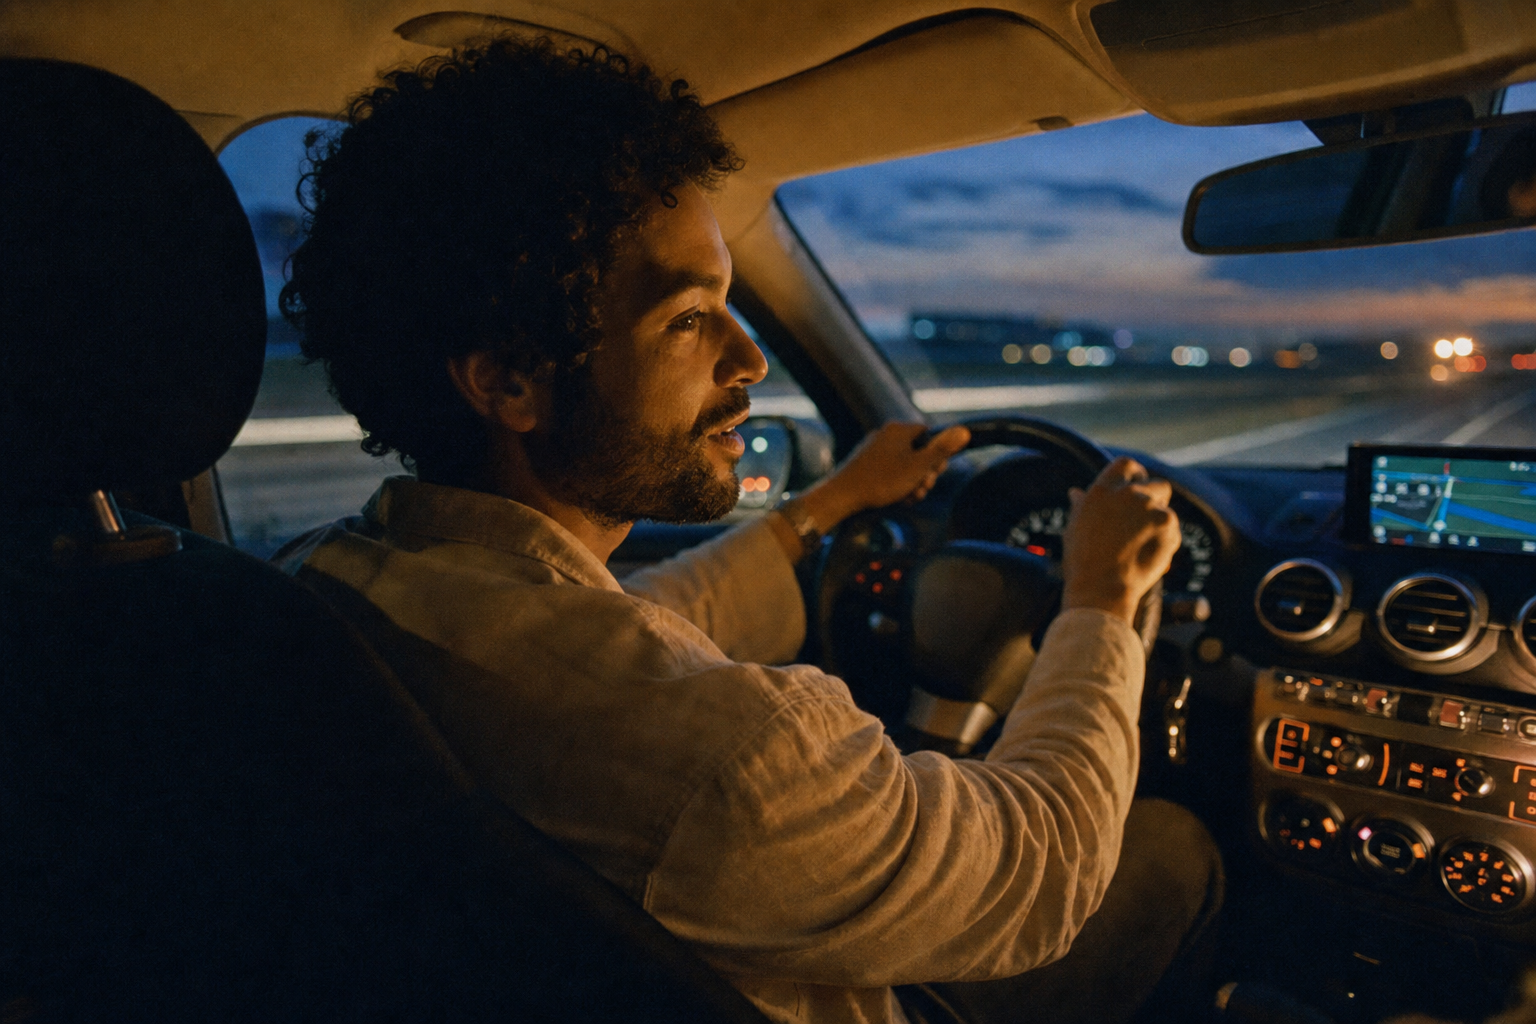
Wearer-aware audio picks up the driver over passengers, HVAC, and road noise. No wake word, no shouting at the dashboard.
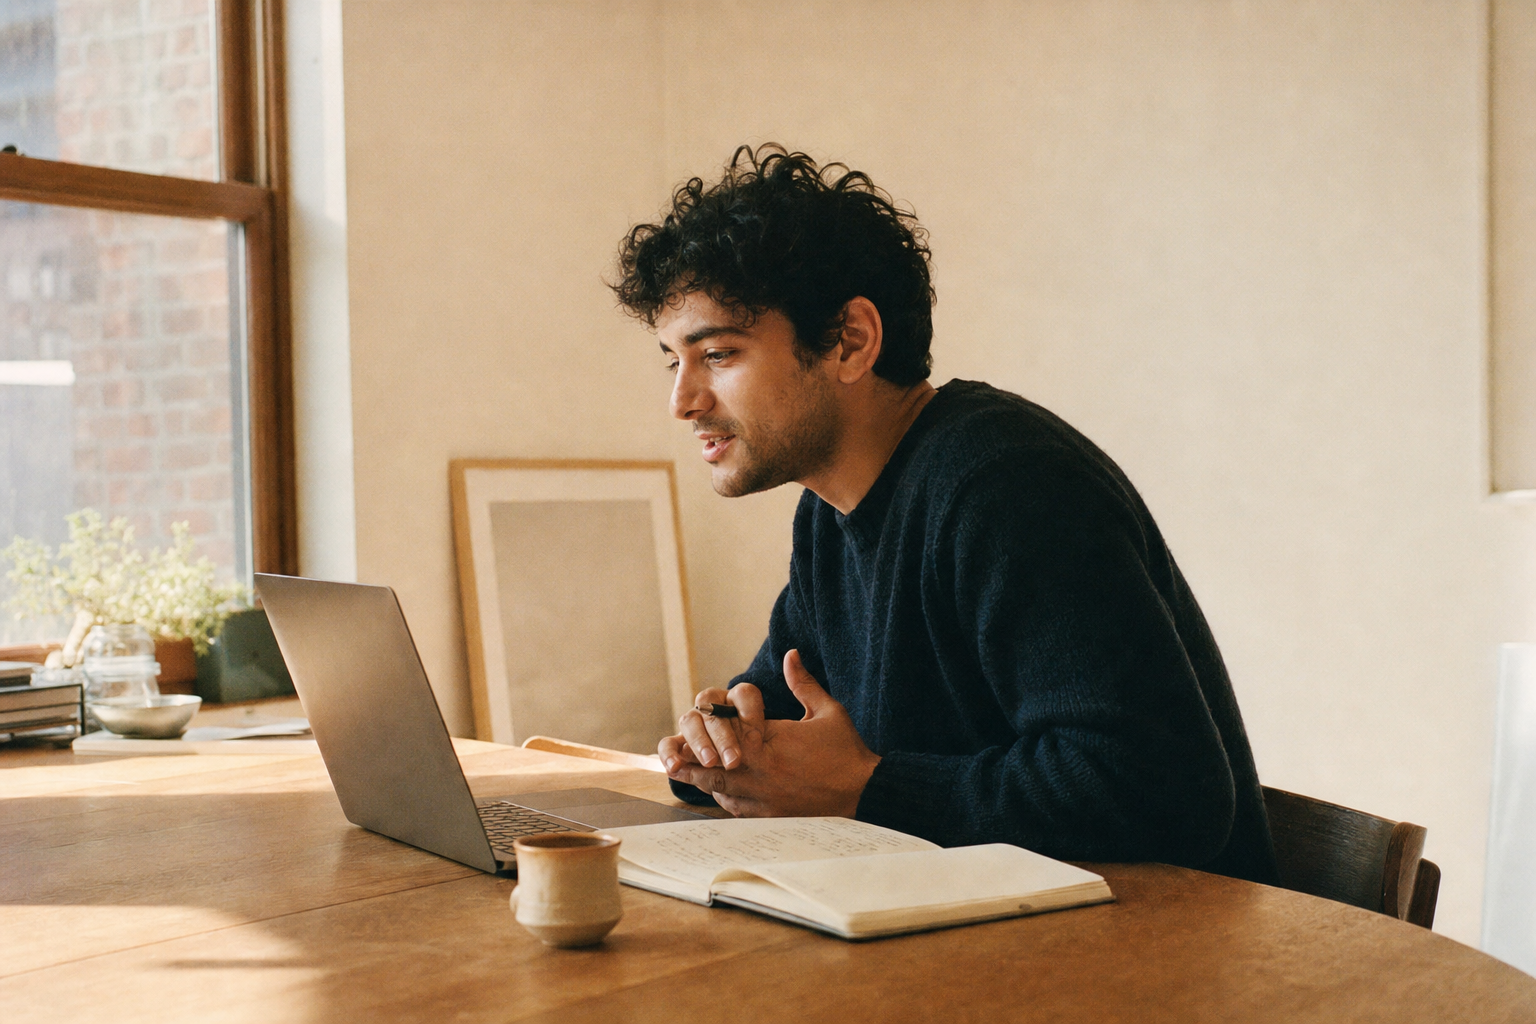
System-wide dictation that works when the office is quiet, the meeting is running, or the room is loud. Same model, same latency, same shortcut.
License them on their own, or as an adaptive stack that switches between voice, whisper, and silent based on the environment.
Whisper or silently mouth anywhere text is entered. iOS, Android, and Mac working today.
Target speaker extraction isolates the wearer’s quiet voice around noise and other speakers.
Visual speech recognition from ordinary front-facing cameras. No audio at all.
Combine visual mouth activity with wearer-targeted audio to know when the wearer starts and stops speaking. Better turn detection, fewer false activations.
Fuse camera and mic streams to recover speech that either modality alone would miss.
Translate a whispered or silent sentence into another language, spoken through the wearer’s earbuds.
API access is early and invite-based. If you are an OEM, tell us the device. If you are a developer, tell us the app.